Brandon RobinsonUnited States, open to relocation. Contact
Systems I built, and what they proved.
The systems on this page run on n8n, Python and TypeScript with Postgres behind them: a 92-node production pipeline delivered to a client, an outbound program measured until its own numbers ended it, and the tools my own work runs on. I specify them, build the workflow graphs myself, direct the code, run them in production, and shut them down when the evidence says so.
I am looking for AI operations, implementation and program leadership roles: the person who puts a system into production and makes a team's use of it real.
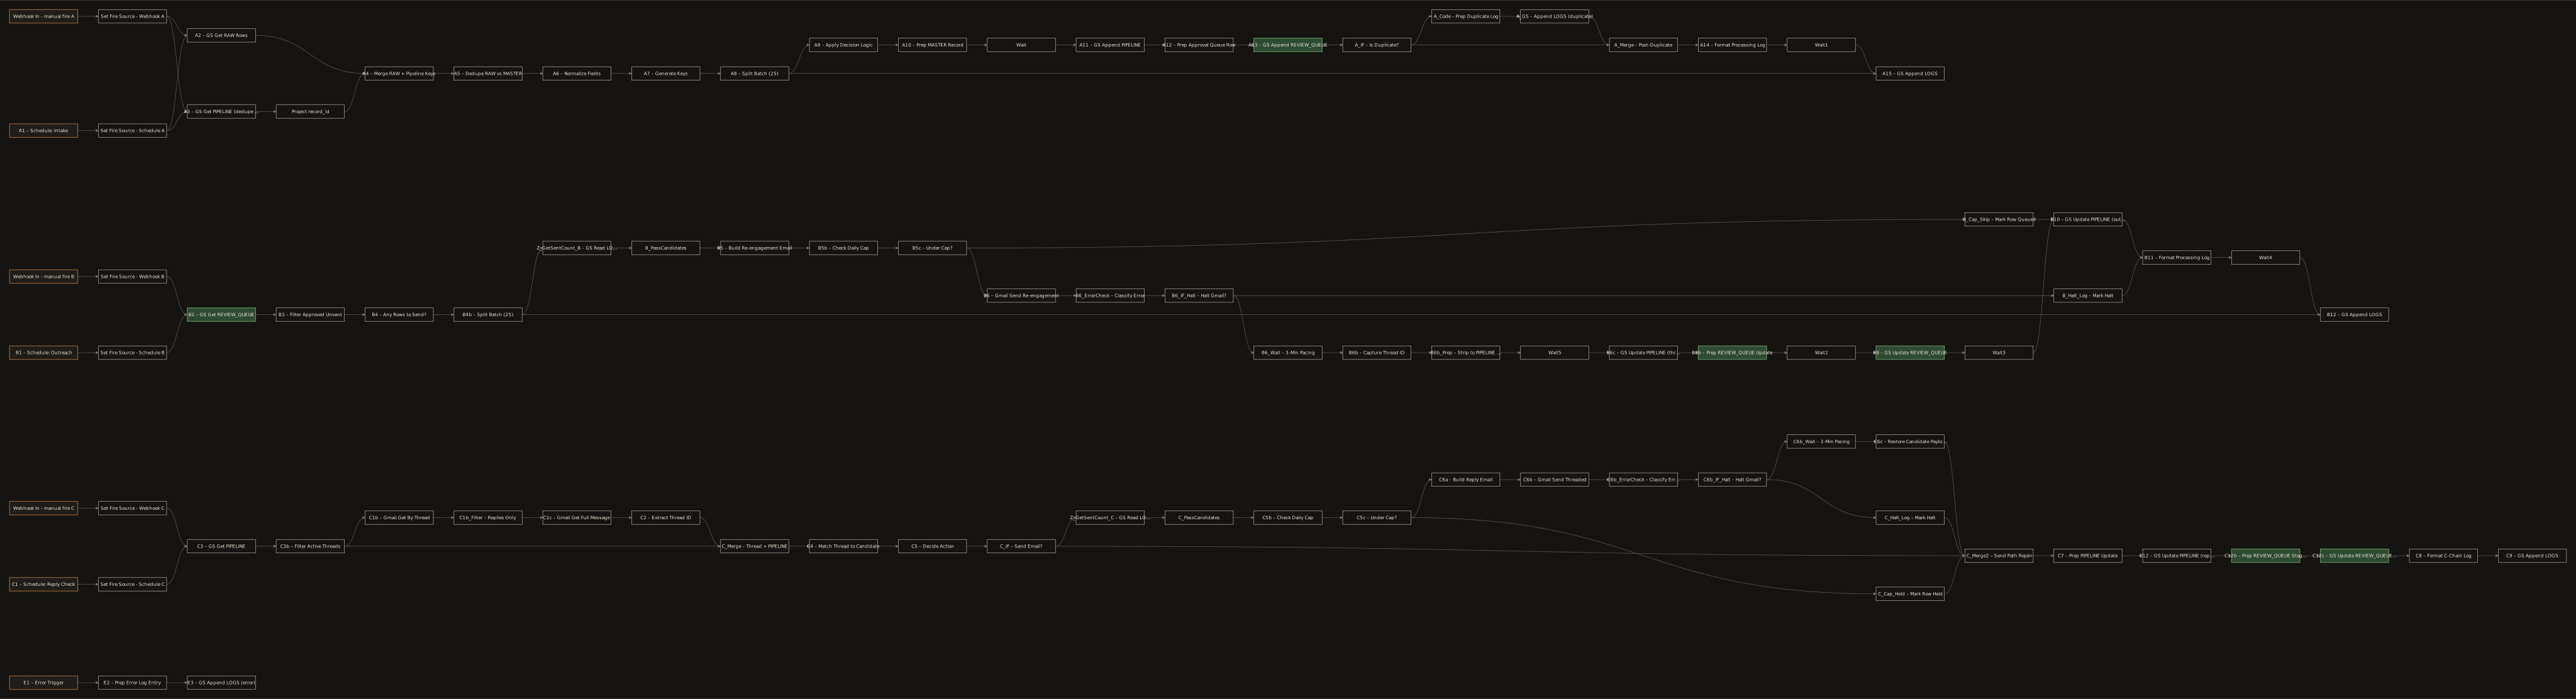
Applicant pipeline. Three chains, one gate, one log.92 nodes, April to July 2026
Written up in full
Full write-ups. Each one ends with what happened after delivery.
An MCP server that exposes only read tools over two operational Notion databases, an audit trail and an action queue, as four native query tools for AI coding clients, with enum values validated against the live schema. Specified by me, code written under my direction, run by me daily.
Live since May 2026; hosted May to September, local sinceNode.js, TypeScriptcode
Six workflows that read receipt email and bank statements into a budget, deduplicated before every write, with a four-state review that routes only the records needing a decision to me. Specified and directed by me.
Running since May 2026n8n, Claude, Notion
A work queue for AI coding agents
Sessions claim work from a board, stop for a person's approval before executing, and write blockers to the record the moment they hit one. Seven skills and a template, in daily use.
Since July 2026Claude Code, Notion
Agents I designed and run
Four of the agents I run, and the operating model that governs them. Each entry takes a minute and includes what broke. Designed, specified, governed and operated by me; the code was written by AI coding sessions under my specifications.
Checks whether a daily written reflection connects the material to the writer or only summarizes it.
Since September 2026Python, Claude Code
Applicant intake and re-engagement pipeline
Client production, April to July 2026. Built by me in n8n; the client's team operated it.
A regional distributor was losing hires between "applied" and "first contact". The gap showed up in their own sheet: rows arriving faster than the contacted column filled in, and follow-up depending on who had time that day. I built the system that closes that gap: three independently scheduled chains that take raw applicant rows, deduplicate and score them, queue the qualified ones for a person to approve, send the re-engagement email, and match every reply back to its candidate.
Applicants processed
10,580
Classification coverage
100%, with 71% filtered out before a person saw them
Nodes in the final graph
92, across three chains and an error subworkflow
Where it ran
n8n on a hardened Linux server, Postgres behind it, Google Sheets as the operator's desk
What decides
Keyword scores and hard pre-gates. No model makes the call.
How it works
Every routing decision, every duplicate, every send and every halt lands in one log sheet, so the question "what did the system do with this applicant" always has an answer. Sends are capped per day and paced three minutes apart. A classified failure halts the chain and writes a halt entry instead of cascading.
Every node in the graph as it ran, drawn from the workflow export. Names only; no parameters, data or credentials. Open it to read the nodes.
Decisions I'd defend
Keyword scores decide who gets contacted, not a language model.Every decision writes its reason to the log and gives the same answer next month. An operator can read the rule and move a threshold. A model would have added a token cost and a second thing to audit on a chain that emails real people. Two months later my evaluation harness measured a related question on public data: the deterministic path within 0.8 points of the best local model at zero token cost.
The operator's desk is a spreadsheet.The client's team already worked in Sheets, so approval is flipping one cell and nobody learns a new tool. The cost is weaker validation and no locking, so the pipeline re-reads the sheet on every run and never trusts a value it wrote last time.
A classified failure halts the chain instead of retrying.An email cannot be unsent, and a retry loop is the one way to contact someone twice. A halt writes a log entry and waits for a person. The daily cap is read from the log itself, so a restart cannot reset it.
What it proved
The client's team ran the approval gate themselves and chose which names to release for outreach, the way it was designed to be run. They used it once, on a stale list, and concluded email did not work for them. It did not become part of how they hire.
Both halves are true, and the second one changed how I scope and hand off every build since.
The number that matters here is not throughput. A three-day silent failure was found by reading the destination sheet, not the run status. The run status said "success".
An outbound email program, measured until its own numbers ended it
My practice, April to August 2026. Full stop on 9 August 2026.
The practice ran on outbound: find small firms losing revenue to a broken intake, reach them with a credible offer. I built the sending system with the compliance and audit chain in from the first send, because the one thing an outbound program cannot recover from is its own domain reputation. Then the chain did its job in the other direction.
Real sends, counted at the mailbox
240
Genuine replies
0
Sent bodies carrying a postal address and an opt-out
238 of 238 verified
Authentication in a real DMARC aggregate
DKIM 29 of 29, SPF 29 of 29
Sourcing pipeline behind it
Five workflows, 87 nodes, verified against the running instance
How it works
Every send-authorizing parameter lives in one configuration sheet: the kill switch, the send window, the per-run caps, the bounce and complaint thresholds. A suppression ledger is checked before every send, and opt-outs are captured from replies twice a day. Every send writes a fourteen-column audit row, and if that write fails the batch halts and the row goes to an inbox instead of being lost.
Decisions I'd defend
The kill switch is a cell in a sheet, not a line in a workflow.Send policy has to be changeable by the person accountable for it without an edit to running code. A false value in one cell stops every run. It was flipped to false when the evidence came in.
Compliance is built in, not checked after.The footer address and opt-out are resolved at one chokepoint the send cannot bypass, which is why 238 of 238 verified bodies carried them. It also meant I could rule out compliance as the cause of silence in one read.
Stop on the evidence.240 sends and no genuine reply is a signal, and the options were warm more domains or find out why. Authentication, blacklisting, domain age and volume were each eliminated from the system's own records. What remained was content filtering, confirmed by the provider's own notice. The program was ended on that finding rather than kept alive on what it had cost.
What it proved
Commercially zero, and provably so. The sourcing pipeline did its job; the outbound program it fed did not, and its own instrumentation said so clearly enough to act on.
Ending a program you built, on its own data, is the part of this I would want a hiring manager to notice.
What is shown here, and what is not
Gate design, audit row schema, the shutdown reasoningshown
Recipients, sender domains, the suppression ledger, any message bodynever
AI output evaluation harness
My practice, June 2026. Scoped and directed by me; the code was written under my direction.
A tool for a question most evaluation tooling assumes away: is the language model the right tool for this classification task, or does a cheaper, auditable deterministic method do the job? The harness runs both over the same labelled cases, scores each against the gold labels, routes low-confidence cases to human review, and emits a comparison report a reader can check.
Attestation
Passed on 11 known-answer checks before any metric was allowed out
Test set
120 public AG News cases; no client data
Deterministic path
Embedding nearest-neighbour, 80.0% at zero token cost
Language models, local
mistral 80.8%, llama3 79.2%
Dependencies
None beyond the Python standard library and a local model server
Decisions I'd defend
No metric ships until the scorer proves itself on hand-computed answers.The only real risk in an offline evaluation tool is a confident wrong report. The attestation suite is that risk's gate, and it is the reason the tool is Tier 1 rather than something heavier.
Zero dependencies, local models.Anyone can run it on a laptop with nothing to install, and every report carries the dataset hash, the model digests and the seed, so a number can be reproduced instead of trusted.
Public data only.The pattern it generalizes came from a client pipeline; the cases it runs on come from a public benchmark. The client's data never enters the repository.
What it proved
The deterministic path came within 0.8 points of the best local model at zero token cost. That answers whether a model was warranted for the task rather than assuming it was.
It was built to portfolio grade and never shipped to a user. That is the honest state of it.
The client pipeline's data, referenced as anonymized narrative onlynever
Axis Core: how my agents are governed
Running since September 2026. Designed, specified, governed and operated by me; the code was written by AI coding sessions under my specifications.
Agents that run unattended are only useful if every change to them, and every miss, is caught by something other than chance.
Axis Core is the operating model behind my scheduled agents, four of which are below, and the AI coding sessions that build and maintain them. I decide. A planning session turns a decision into a written, scoped work order. A coding session claims the order, does the work and writes the outcome back onto it before it may close. The night agents run on a schedule and report to me each morning. Everything lands in one record.
Who does what. The dashed line is Warden comparing the record with what the systems show.
Work orders completed through it
248 since July 2026, as of 30 September 2026
Decisions on the record
More than 1,000, as of 30 September 2026
Before a change to an agent goes live
Its test suites pass and its schedule matches one timing manifest; a major change also passes an end-to-end dry run
Two agents were moved to earlier slots and their dead-man checks were not. The next night both ran clean, finished their work and sent their success signals, and both were reported down at exactly the old schedule plus its grace period. A monitor that is not moved with the thing it watches does not lose coverage; it inverts, and a false alarm every morning teaches its owner to ignore the real one.
Fixed the same day with a rule that a schedule change moves its check in the same session. Two weeks later it became mechanical: one timing manifest, and a script that moves the task, the check and the agent's configuration together and reads all three back.
My part: I designed the operating model and its division of authority, specify each agent and each change to one, and approve what an agent may not decide alone.
Aegis: the morning brief
Running since September 2026. Designed, specified, governed and operated by me; the code was written by AI coding sessions under my specifications.
Morning triage across mail, calendar, open tasks and system health was mine to do by hand, every day.
Every night Aegis reads my mail, calendar, open action items and the health of my other systems, and writes one brief before I start, led by what to act on today. Since October 2026 it also sorts new mail as it arrives and messages me privately when something needs me now. It labels mail and clears noise out of the inbox, and it is not allowed to delete. It can undo its own labels and keeps my own tracking records up to date. It is not allowed to send to anyone but me.
Trigger, decision, what it may do, and what it never does.
One-time backlog pass, one inbox
2,142 of 4,143 messages labelled, 0 errors, read back from the mailbox; nothing left the inbox
Protected from sorting by a safety check
614 messages
What broke, and the fix
In the first test batch for mail sorting, one account-security notice was sorted as noise. The safety check was widened to protect that kind of mail before the full backlog ran, and in that run nothing left the inbox.
The same honesty applies now. Since October Aegis labels and moves mail, so it is no longer described as read-only anywhere. It is report-and-sort: it is not allowed to delete, and it messages only me.
My part: I specified what it reads, what it may change and what it must never do, and approved each widening of what it may do.
Kestrel: the night dispatcher
Running since September 2026. Designed, specified, governed and operated by me; the code was written by AI coding sessions under my specifications.
Some document and research work is specified well enough to run overnight, if the run can be trusted unattended.
Kestrel is a night dispatcher that handles documents and research for specific night tasks. It runs after Aegis's slot each night. The night runs as five staged model sessions: lighter stages on a smaller model, judgement and document builds on a larger one. It researches the open web through parallel workers that save each source page verbatim. It leaves a queue for my review in the morning.
The morning email goes out from a separate mailer with one fixed recipient.
Model sessions per night
Five, staged
Seam tests between the stages
148 checks
End-to-end dry run before the research stage went live
124 minutes, passed
What broke, and the fix
Its first live night succeeded and reported failure. The runner checked a timestamp as text after the JSON parser had already turned it into a date, so a fully successful run pinged the failure alarm, pushed "run failed" and skipped the morning email. Fixed by comparing the values as times.
Later, a single network miss could cost the whole night. Each stage now waits for the network and picks up the same session where it stopped, within a retry budget, and any alarm the outage kept from being delivered is held and retried after the run.
My part: I specified the night tasks, the stage split and its limits.
Warden: the record checker
Running since September 2026. Designed, specified, governed and operated by me; the code was written by AI coding sessions under my specifications.
A written record of how systems behave drifts from how they actually behave, and nothing announces it.
Every morning after the night agents finish, Warden re-derives facts about my systems from the systems themselves: scheduled tasks, run logs, workflow flags, code constants, database counts and page dates. Then it compares each one with what the written record asserts. It has no language model. It acts in three tiers: it corrects only counts it derives itself, logging the old and new value; it proposes prose changes and waits for my approval; and everything else it only reports.
A canary fact with a deliberately inverted check must fail every run; if it ever passes, both write stages are skipped.
At write-authority go-live, 12 September 2026
59 facts: 45 matched, 10 drifted, 2 informational, 2 not yet given a check, 0 unreadable
Proof harness on the same day
9 of 9, with the canary detecting inversion
Reverse index built at launch
1,751 artifacts and 7,275 links between them
Language model
None
What broke, and the fix
Another agent changed the shape of a file Warden reads: a bare list became an object carrying a count. One unreadable fact out of 59 then stopped every later step of the run, including four corrections, the run record and the status message. Now a partial run still raises an alarm, then runs every remaining step, acting fact by fact. File readers accept both shapes and treat a count that does not match as a truncated read. A file passed between two agents is an interface, not just a file.
Earlier, its write check asked whether the new text was present and the old text gone. That reports a correct edit that quotes the text it replaces as a failure. It now compares what it reads back with the exact text it sent.
My part: I specified the fact base, the three tiers and the proof gate, and I approve or decline every prose change it proposes.
A private reflection-depth agent
Private, running since September 2026; the depth check since October 2026. Designed, specified, governed and operated by me; the code was written by AI coding sessions under my specifications.
A daily written reflection is only useful if it connects the material to the writer. A summary is easier to write and teaches nothing.
I write one short reflection a day. The agent checks whether it connects what I read to me, or only summarizes it. If it only summarizes, or is still empty in the evening, it nudges me privately the same day. The next morning it sends back two or three of my own sentences, verbatim. The daily check is deterministic: no language model, and it makes no writes. In the morning step a model may only pick sentences, never rewrite them.
Trigger, decision, what it may do, and what it never does.
Labelled test set
21 days of entries, labelled by the build session before the rule was written
Agreement with the labels
20 of 21 days; all 4 summary-only days caught, 1 genuine reflection wrongly flagged
Morning return, claims not in the entry
0 of 18
Language model in the daily check
None
What broke, and the fix
The first design of the morning step paraphrased my entries. 13 of 18 paraphrases passed an automatic word check, and a hand read then found 2 of those 13 changing my meaning by dropping a short qualifying phrase. The word check could not see it, because every word it tested was still mine.
Paraphrase was rejected. A model now only picks two or three of my sentences, and they are sent verbatim in quotation marks: 0 of 18 claims not in the entry. Accuracy over polish.
My part: I set its purpose and rule on the questions its builds hold for me. The connection rule and the test labels were drafted by the build session.
Personal financial operations pipeline
Personal, running since May 2026. Specified and directed by me.
Six n8n workflows: receipt email is read by a language model into structured rows, bank statements are read by a vision model, and a daily job links every row to its budget line. Every row is checked against what is already stored before it is written, so re-running a month adds nothing twice. A four-state review routes only the records that need a decision to me; I do not look at every record, and the design does not ask me to. Nothing from it is shown here beyond the design; it is my money.